Perplexity Photon: cheaper search for AI agents, with a workflow test first
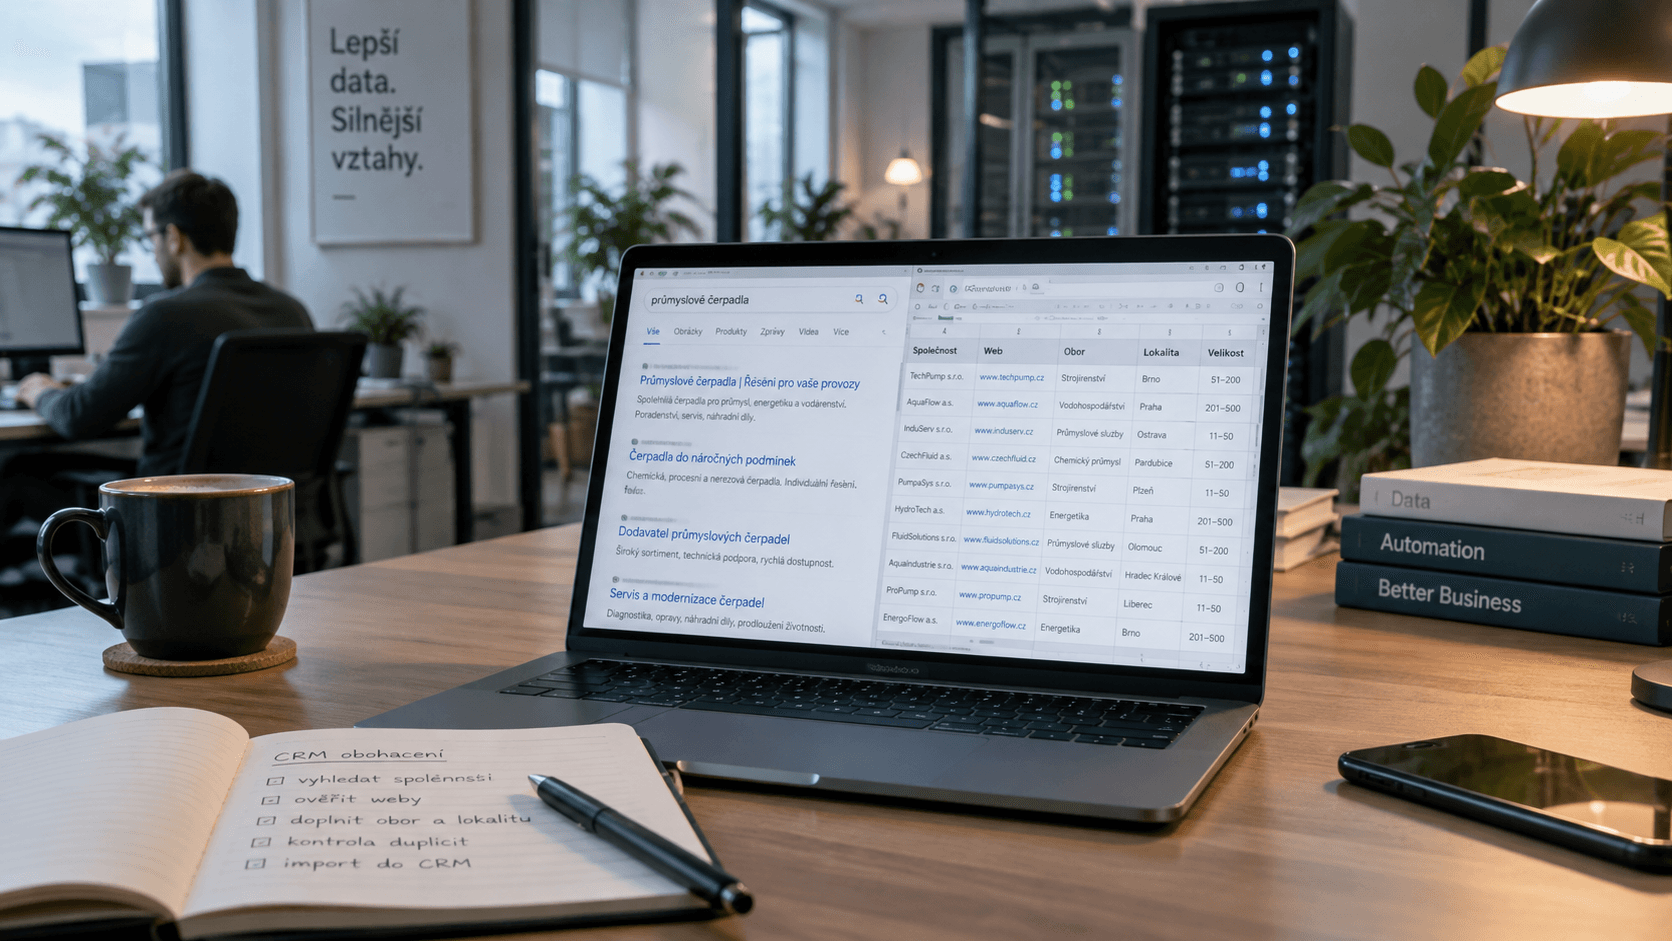
An agent enriching company records in a CRM may spend more time finding evidence than waiting for its language model. Alongside model selection, I would measure the search step: its cost, the evidence it returns and how many retries follow.
On September 24, 2026, Perplexity introduced Photon, its own retrieval and ranking engine, and Fast Search. It reports 68% lower estimated model-plus-search costs across six agent benchmarks with comparable aggregate success. These are vendor measurements; the faster option performs less well on broader, ambiguous searches. Research article, publication date.
Search cost is only part of the bill
The price list puts standalone Search API at $1 per 1,000 successful Fast Search requests versus $5 for standard search. Billing is per request, including empty results; Search API adds no token fee. Budget separately for the model that processes those results.
For 10,000 requests, that means $10 instead of $50: an 80% reduction in the search line item, distinct from the 68% benchmark figure. But if faster search causes repeated queries or an incorrect company profile, the complete workflow can cost more. The useful metric is cost per correctly enriched record.
A proposed n8n or Make workflow
This is a pilot design, not a deployment I have tested:
- Take the public company name and known domain from the CRM. Do not send the entire internal sales opportunity to a search service.
- Use an HTTP step to find the official website and evidence for one field, such as industry or registered location.
- Have an extractor return the value, source URL, check date and an “supported / unclear” status. Missing evidence leaves the field empty.
- If domains conflict, names match multiple companies or evidence is insufficient, try standard search. After one retry, hand the record to a person.
- Write to the CRM only after validation. Keep the previous value and an operation identifier so retries cannot apply the same update repeatedly.
This separates finding evidence from authorizing a database change. It also works as a design pattern for a content research pipeline or public-documentation lookup in support. For internal email classification that needs no web evidence, I would omit search entirely.
Configuration and an SDK trap
For POST https://api.perplexity.ai/search, set search_type to fast. The response format is unchanged; omitting the parameter selects web. Fast Search differs from the Agent API’s fast preset. Python SDK versions 0.43.4 and 0.43.5 need extra_body={"search_type": "fast"}. Fast Search documentation.
For an initial pilot, use an HTTP node with securely stored credentials and a small record set. That makes it easier to distinguish service responses from library validation errors. This configuration has not been verified here with a production account.
What the pilot needs to prove
Start with, say, 100 manually checked companies, including duplicate names and missing websites. Run both modes against the same set. Compare field accuracy, human handoffs, retries, total cost and completion time. Record the evidence date too: a live website may still carry outdated information.
I would adopt cheaper retrieval where those results hold up. If corrections erase the savings, keep standard search or revise the routing rules. That test determines what Photon is worth to the business.